- SPECIMEN
Firecrawl
- FILED AS
Web data API that searches, scrapes and crawls pages into LLM-ready output
- INTAKE DATE
- 2026-09-28
- CLASS
- AI Platform
- METHOD
- 2 pages scraped, 3 search passes, 10 community sources
Search, scrape, crawl and browser interaction share one API with structured JSON output built in, though social platforms and multi-step enrichment remain gaps. THE RUNDOWN
A free account, Python and Node SDKs and a CLI get a developer to a first scrape fast, while non-coders have no easy path in. ZERO TO RUNNING
The free monthly allowance is generous for testing, but structured-format surcharges and the steep jump from Hobby to Standard make heavy extraction expensive. THE DAMAGE
A Reddit thread in r/scrapingtheweb cites 104K GitHub stars for the project, a strong traction signal even as other threads question its value. reddit.com
Koda Score = weighted blend: capability 35, ease 20, value 25, momentum 20.
Clean markdown and JSON output remove the most tedious part of feeding the live web to a model, and the free tier is large enough to prove that on your own target pages. Developers wiring search and scraping into agents should adopt it. The cost only bites once structured extraction runs at volume, so model your credits before you scale.
Firecrawl turns a URL into LLM-ready markdown or JSON with one API call, and the credit math deserves more of your attention than the setup does.
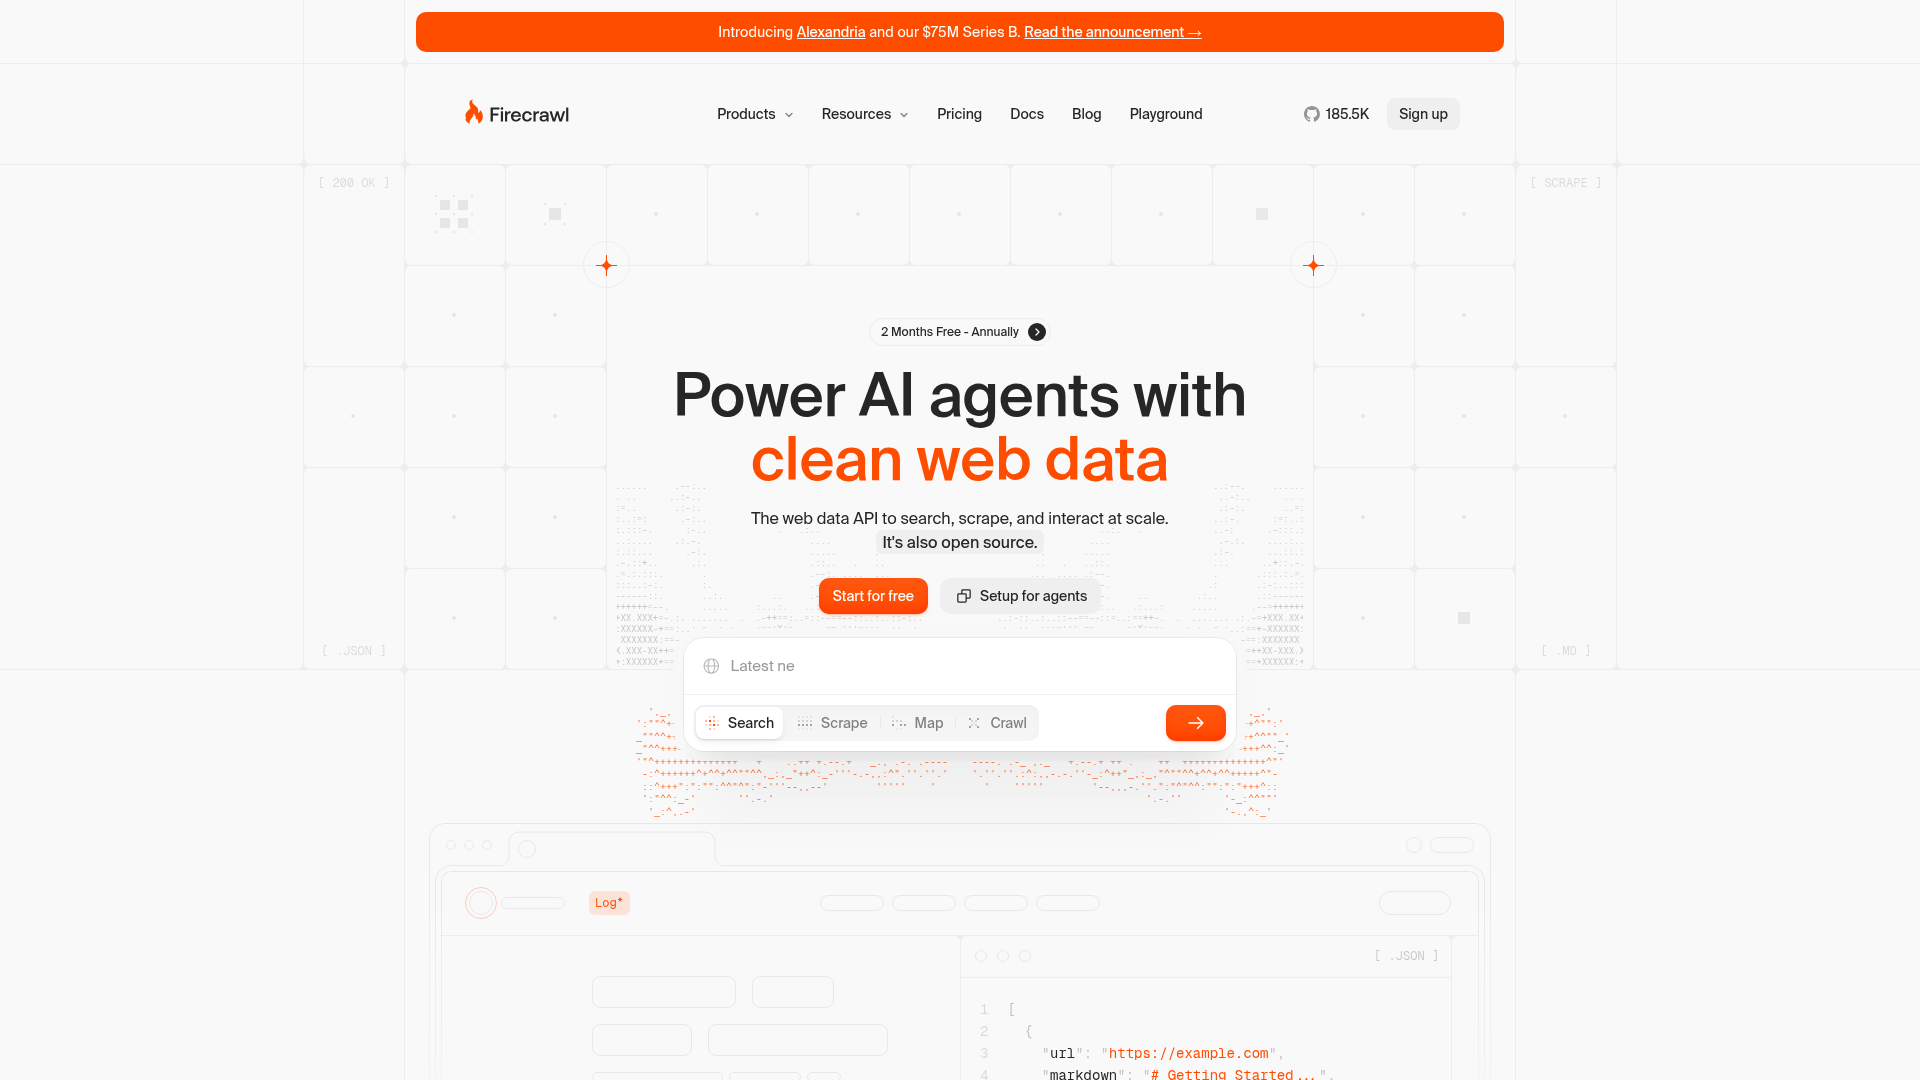
Captured: www.firecrawl.dev on 2026-09-28.
The short version.
4 LINESStart on the free plan and scrape your own target pages before paying anything.
Budget JSON extraction separately, because format add-ons multiply what each page costs.
The gap between Hobby and Standard is wide, so estimate monthly page volume before you pick a plan.
Non-developers should look at a no-code tool from the start.
What it actually does.
6 CAPABILITIES- Search
- Runs a web search and returns full page content from the results in the same call.
- Scrape
- Converts a single page into clean markdown or structured JSON ready for a model.
- Crawl
- Follows a site beyond one URL and draws every page from the shared credit balance.
- Interact
- Drives a live browser to click through and operate pages that need more than a fetch.
- Agent setup
- Ships a dedicated setup path for plugging Firecrawl directly into AI agents.
- Open source core
- The project code lives in a public GitHub repository you can inspect or run yourself.
How you would actually use it.
3 PLAYS- Pricing-page trust test
- Scrape three competitor pricing pages with the JSON format and have your agent merge them into one comparison table. Then open each vendor's page in a browser and check every number by hand.WHOFounder doing competitive researchPAYOFFProof that extraction holds on messy real pages before you wire it into a larger research loop.
- Search-to-context pipeline
- Hand your agent the Search endpoint as a tool and pipe the returned markdown straight into its context window, skipping any custom parsing layer.WHOAI engineer building a research agentPAYOFFAn agent that reads current web sources without a hand-rolled scraper to maintain.
- Credit budget rule
- Before any crawl larger than a few hundred pages, multiply page count by the per-page cost including format add-ons. If the total exceeds your plan's monthly credits, set a pay-as-you-go ceiling first.WHOTeam lead watching spendPAYOFFNo surprise overage at the end of the month.
Pricing, straight.
4 TIERS- Verdict on the price
- Plain scraping at 1 credit per page is fair across every tier, and search costs 2 credits per 10 results, but anyone relying on structured output should price plans against the surcharge before committing.
What people online are saying.
5 QUOTEDBuilders praise the clean, LLM-ready output and quick setup, while Reddit threads push back on credit costs and the self-hosted build.
A reviewer said it finally let them reliably pull meaningful data out of unstructured web content, and that it felt almost magical.
PraiseCrewdle picked it over building their own crawler because it returned clean markdown, coped with JavaScript-heavy sites and rate limits, and had them running in an afternoon.
PraiseOne commenter said it is a bad choice for scalable scraping unless you want to burn money.
CritiqueA user complained that the open-source claim rings hollow because the self-hosted version performs poorly.
CritiqueThe honest part.
4 LIMITATIONSOn Scrape and Crawl, the JSON format and its sibling formats add 4 credits per page, so extraction runs cost several times what plain scraping does.
Social media platform data is a weak spot, according to Gumloop's hands-on review.
It is developer-focused, leaving anyone who wants a point-and-click scraper without a good option.
Product Hunt reviewers want deeper multi-step search that expands to related sources automatically when the starting context is incomplete.
The field.
3 ALTERNATIVES- Apify
- Scraping platform with an Actor marketplace, scheduling and broad framework support.PICK IT WHENYou run many varied scraping workloads on a schedule and want ready-made scrapers.
- Tabstack by Mozilla
- A no-scraper extraction approach suggested by Product Hunt users.PICK IT WHENYou want web data collection without running scraping jobs yourself.
- ApyHub
- Plug-and-play API offering positioned as a simpler integration.PICK IT WHENYour priority is the lightest possible integration effort.
Getting started.
3 STEPSCreate a free account from the Firecrawl homepage.
Copy your API key and install the Python or Node SDK, or use the CLI.
Scrape one URL and inspect the markdown and JSON output before scaling up.
Quick answers.
4 ANSWERS- Do I pay for pages that fail?
- A scrape that returns no result is not charged. A page that answers with an error status such as 403 or 404 is still returned to you and costs 1 credit.
- Can I self-host Firecrawl?
- You can, since the repository is public. Reddit users running it for themselves describe the stack as bigger than a single user needs, and at least one swapped it for a custom scraper built with their agent.
- What happens when my credits run out?
- Paid plans can enable pay-as-you-go, which adds credits in $5 increments up to a monthly limit you set. Free-plan users wait for the monthly refresh.
- Is the company stable enough to build on?
- Firecrawl announced a $75M Series B alongside the launch of Alexandria, which it calls a knowledge library for superintelligence. Its site also claims more than 150,000 companies as users; treat that as a vendor figure.
The bottom line.
SPECIMEN 0235 CLOSEDRun the pricing-page test on the free plan this week. If the agent's table matches what the vendors actually publish, Firecrawl earns a slot in your agent stack.
Field research: 2 pages scraped · 3 search passes · 10 community sources. Reviewed by the Koda desk on 2026-09-28.