K Koda Intelligence
Subscribe
Cover image for the 18 October 2026 Signal: Reflection AI's Beam ships 501 billion parameters under Apache 2.0, yet trails Kimi K3 by 8.2 points on Terminal-Bench v2.1.
THE SIGNAL · 18 OCT 2026 · 9 MIN READ

Reflection AI opens Beam under Apache 2.0, but Kimi K3 still leads

Reflection AI released Beam, a 501B1-parameter MoE model, with open weights and a score of 80.1 on Terminal-Bench v2.1. It lands as open-weight models carry most of the token traffic.

AIOPEN WEIGHTSAGENTS
28 of 34 figures cited13 receipts in the register
  1. 501B1Hugging Face
  2. 71.5%2The Register
  3. 23%3The Register
The register
Lead Story

The day's defining move.

Open Source · Hugging Face
Lead storyOpen Source 501B1 Hugging Face · EDITION 18 October 2026
Open Source·Hugging Face·EDITION 18 October 2026

Reflection AI Opens Beam, a 501B1-Parameter MoE Model

Reflection AI posted Beam's weights under Apache 2.0; it scores 80.1 on Terminal-Bench v2.1, below GLM-5.2 (81.0) and Kimi K3 (88.3).

Why it mattersBecause Beam's weights are under Apache 2.0, teams can self-host and fine-tune it commercially, though agentic coding work that demands the best Terminal-Bench v2.1 results still favors Kimi K3.

Continue reading
Markets

The Nasdaq fell 2.15% and the S&P 500 lost 1.09% while WTI crude rose 3.51%, leaving oil as the only listed asset to gain on the session; Bitcoin was flat, Ether slipped 0.58%, and the crypto Fear & Greed index read 53 (Neutral).

Wild Card

Open-weight models now handle 71.5%2 of tokens but draw only 23%3 of spend, so a free Apache 2.0 release like Beam adds to the usage side of a market where most of the money still flows elsewhere.

KODA PROFrom the desk

The Operator Tier is coming.

A weekly operator deep dive, the full Dojo Pro prompt packs, and the complete prompt database. Founding members lock the launch price forever.

Join the founding list →
Listen & Watch

Daily broadcasts.

Podcast · Video · Infographic
YouTube · Short

Today's Signal Short

Visual

Intelligence map

Markets

6 levels at the close.

Market TerminalLAST CLOSE 16 OCT 2026 · READ 2026-10-18 · Yahoo Finance
S&P 500 7,659.447 -1.09%7 6D, window short 7,659.44 low / 7,811.54 high
Nasdaq 26,140.038 -2.15%8 6D, window short 26,140.03 low / 27,366.17 high
Bitcoin $81,497.639 -0.00%9 6D, window short $81,497.63 low / $83,095.12 high
Ethereum $2,405.7910 -0.58%10 6D, window short $2,405.79 low / $2,496.63 high
Crude Oil (WTI) $101.4111 +3.51%11 6D, window short $91.85 low / $101.41 high
Crypto Fear & Greed 53 / 10012 Neutral 0 to 100 index 25 fear / 50 neutral / 75 greed · alternative.me
Today's Focus

What else the day turns on.

01

Gemini 4 Argon Decision Guide

A featured guide covers Google's newly opened Gemini 4 Argon, a model built for long, multi-step work that current setups struggle to finish. It argues that most daily tasks do not need the stronger model and lays out a decision process for choosing between Argon, Flash and Flash-Lite.

02

Muse Spark Open Reaches Macs

Muse Spark Open reaches Macs as Meta released weights optimized for Apple silicon, but running it requires at least two top-spec M5 Ultra Mac Studios. Meta AI chief Alexandr Wang told Axios the two companies are 'playing nice again.'

The Lab

Tool of the day, researched.

All Lab reports
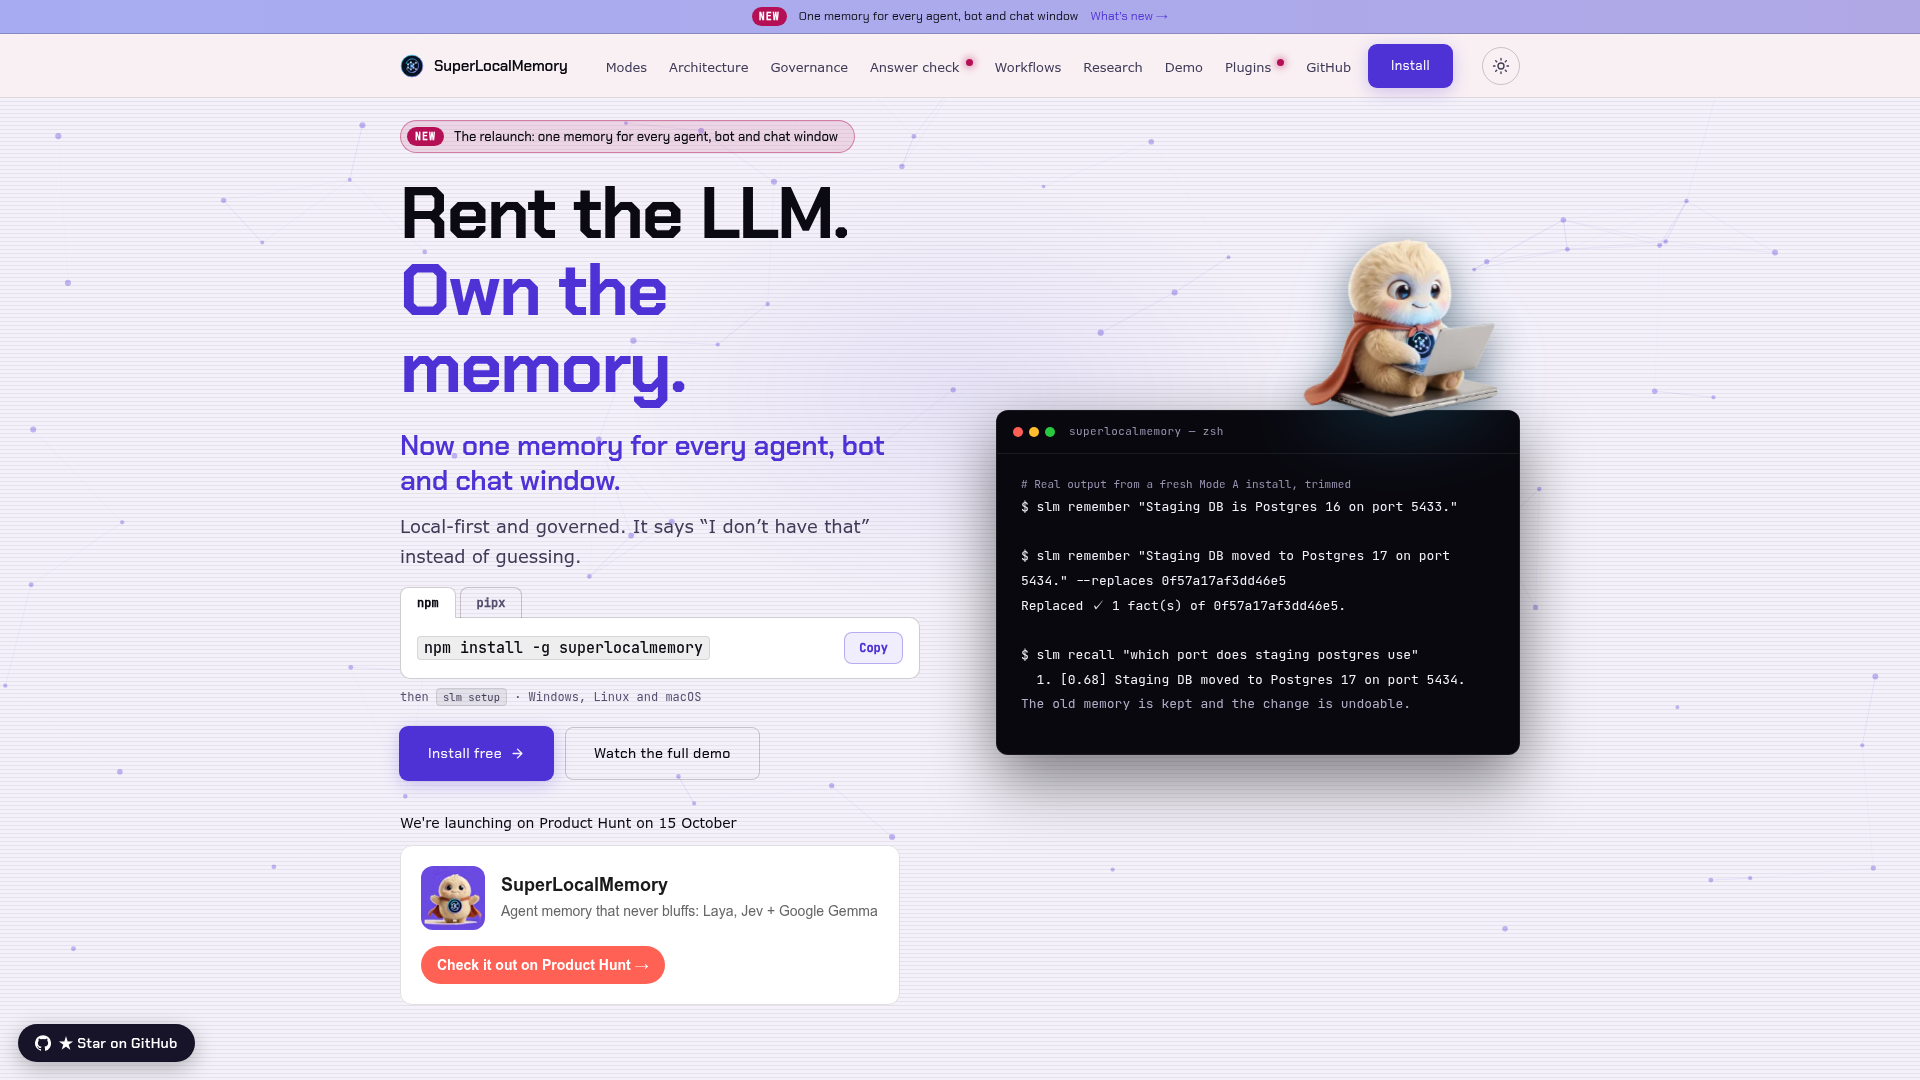
SuperLocalMemory home page, captured for the 18 October 2026 Lab report Tool of the day 7.413/ 10
Coding

SuperLocalMemory

Every recall from SuperLocalMemory comes back graded, so a coding agent about to bluff about your staging port gets caught before it acts.

SuperLocalMemory grades each recall and keeps replaced facts on an undoable record, which targets the costliest failure in multi-agent coding: an agent acting confidently on stale context. The free local core means a trial costs one install, and developers running two or more coding agents on one repo should take it this week. Keep it a personal tool until the paid plans carry real numbers.

Capability 7.5
Ease 7.0
Value 8.0
Momentum 7.0
Also on the radar
Coding

CtxWise: trim the MCP context your coding agent burns tokens on

CtxWise tree-shakes MCP tool schemas so your coding agent loads only the definitions it needs, which lowers context usage. It also adds firewall controls that restrict which tools an agent can reach. Run one typical task with and without it, compare the token counts, then use the firewall to block any MCP servers that task never needs.

Try it
Coding

Paveo: check agent commands and file writes before they land

Paveo sits between you and agents such as Claude Code, Codex, and Cursor, inspecting the shell commands and file writes they issue. Every action goes into a hashed audit log, so later edits to the record are detectable. Turn it on for agents that touch production config or deployment scripts, and review the log after each session to see what actually ran.

Try it
Productivity

Auxx.ai: open-source customer support with an AI copilot

Auxx.ai is an open-source support platform. Its Kopilot assistant uses text classifiers to sort incoming tickets and drafts context-aware replies for agents to approve. Because the code is open, small support teams can self-host it and inspect how tickets are routed before letting it draft responses to real customers.

Try it
Creativity

Everygen AI: generate video and image content from one tool

Everygen AI, previously called Viewmax, creates both video and image content for marketing, social, and other uses. Keep your still images and short clips in one place by drafting a campaign's visuals and companion video together. Then compare the output against your current workflow to see whether it saves a hand-off between separate tools.

Try it
The Arena

3 labs moved this week.

  1. Google DeepMindDeepMind's safety report says Gemini 4 Argon has not produced significant end-to-end acceleration of AI research. ixbt.com · 18 OCT 202601
  2. AnthropicAnthropic has given six METR staff members employee-like access to its models, tools and San Francisco office. sfstandard.com · 17 OCT 202602
  3. OpenAIOpenAI is finalizing contracts with external organizations to evaluate its models. sfstandard.com · 17 OCT 202603
Builder Radar

One paper, read at the source.

Primary sources, pulled by index
Paper of the day

Agent-Reflex: Teaching Language Agents to Act Reflectively

Guanting Dong, Xinyu Yang, Jiajie Jin et al. · arXiv 2026-10-13

Large language models have evolved from single-turn chatbots into interactive agents capable of long-horizon reasoning.

- • EnvScaler [Song et al., 2026] constructs executable environments with verifiable outcomes and is the strongest environment-scaling baseline in our tables; because the ORPO stage of Agent-Reflex reuses its RL task pool, it is the reference for attributing...
Read the paper

The paper comes from the Firecrawl Research Index: arXiv, indexed in the last 7 days and submitted this month or last, picked for today's lead. Quotes are verbatim.

THE DOJO · BUILD TODAY

Test open weights against your own agent workloads

  1. 01

    Run Beam on your own terminal tasks. Pull the Apache 2.0 weights and replay ten real shell-heavy jobs from your backlog. Log pass rates next to your current model, since a public leaderboard score will not match your repo.

  2. 02

    Price a routing split. Pull a week of gateway logs and tag each call by difficulty. Send the routine, high-volume traffic to an open-weight model and keep a closed model for the hard cases, then compare the bill.

  3. 03

    Trial SuperLocalMemory on one multi-agent repo. Start with the free local core and review how it grades recalls and logs replaced facts. Roll back one deliberately stale fact to confirm the undo record works.

The Bottom Line

Open weights are getting cheaper to run and easier to license, so measure before you switch.

Beam arrives with a permissive license just as gateway data shows open-weight models taking a growing share of paid usage, which makes a self-hosted trial a practical question rather than a hobby. The benchmark order still matters for hard agentic coding, so judge Beam on your own workloads and not on the headline score. Pair that test with a memory layer such as SuperLocalMemory so stale context does not skew the results. Start with a small routed slice of traffic this week and expand only where the numbers hold.

Receipts

Every number, and where it came from.

28 of 34 figures cited, 13 receipts: 2 verified, 10 reported, 1 estimated
  1. 01501BReflection AI Opens Beam, a 501B-Parameter MoE Model.Hugging Face18 OCT 2026as publishedR
  2. 0271.5%Open-Weight Models Take 71.5% of Tokens, 23% of Spend.The Register17 OCT 202603B search corroborationV
  3. 0323%Open-Weight Models Take 71.5% of Tokens, 23% of Spend.The Register17 OCT 202603B search corroborationV
  4. 042.8TMicrosoft details MAI-Base-2, a 2.8T-parameter mixture-of-experts model with 80B active parameters that it says beat...Microsoft, via TLDR16 OCT 2026as publishedR
  5. 0580B...MAI-Base-2, a 2.8T-parameter mixture-of-experts model with 80B active parameters that it says beat every open-weight...Microsoft, via TLDR16 OCT 2026as publishedR
  6. 06$0.042...real-world tasks like circuit-board defect detection, priced at $0.042 per million input tokensLiquid AI, via TLDR16 OCT 2026as publishedR
  7. 077,659.44S&P 500 close, -1.09% on the sessionYahoo Finance16 OCT 2026yfinance closeR
  8. 0826,140.03Nasdaq close, -2.15% on the sessionYahoo Finance16 OCT 2026yfinance closeR
  9. 09$81,497.63Bitcoin close, -0.00% on the sessionYahoo Finance18 OCT 2026yfinance closeR
  10. 10$2,405.79Ethereum close, -0.58% on the sessionYahoo Finance18 OCT 2026yfinance closeR
  11. 11$101.41Crude Oil (WTI) close, +3.51% on the sessionYahoo Finance16 OCT 2026yfinance closeR
  12. 1253 / 100Crypto Fear & Greed close, Neutral on the sessionalternative.me18 OCT 2026as publishedR
  13. 137.4 / 10SuperLocalMemory, Koda score across four dimensions04R dossier18 OCT 202604R dossier scoringE
V
Verified: the stat gate corroborated this figure against an independent search before publication.
R
Reported: the figure is carried as published by the linked source and was not independently corroborated.
E
Estimated: the figure is approximate or hedged, either in the source or by the stat gate.

Method names the computation path behind the row, from a closed vocabulary: as published, yfinance close, 03B search corroboration, 04R dossier scoring, not recorded.

A figure is money, a percentage, a spelled magnitude, a multiple, a rate carrying its unit, a score over its denominator, a thousands separated number or an index close. Bare integers and years are not counted, so a phrase like "over 100 integrations" carries no mark. A chart's own scale line is the axis of the level above it and is counted once, with that level.

Get the morning Signal

205 editions so far, one a day. Unsubscribe anytime.

Forward this to one operator you work with. Your referral link is in every email; milestones at koda.community/refer.